

Here’s an invented scenario. A service vice president approves a “quick Agentforce proof of concept” in a hallway conversation. After 6 weeks, the team shows a polished demo of an agent answering 12 hand-picked questions, and the finance chief asks whether to fund production. Nobody can answer. Nobody wrote down what success meant, how many cases were tested, what the agent would cost per conversation, or who would own it afterward. The demo worked. The pilot produced no decision, and the team spent the next quarter arguing about what it had proved.
This guide shows how to scope a 6-week pilot so that it ends in a decision. It draws on public sources that all have a stake in the answer. Salesforce’s admin blog and Trailhead are vendor material. Girikon, Credera, Customertimes and Vantage Point are consultancies, and Salesforce Break is run by a consulting partner. Gartner’s forecast reached me through a republished press release, because its own page didn’t load. I found no study that measures pilot outcomes in Salesforce orgs. Every hour, dollar and threshold in the work plan is invented, so confirm pricing and product behavior with Salesforce before committing.
TL;DR
- Scope the pilot for a decision. Gartner predicts over 40% of agentic AI projects will be canceled by the end of 2027, citing cost, unclear value and weak risk controls, and says most current projects are early experiments or proofs of concept. A 6-week pilot should end in go, extend or stop, against criteria written in week 1.
- Keep it narrow and measurable. Use a single workflow, a single user group and controlled data. In the invented plan, 388 hours cost $51,400 and credits add about $520, yet a 200-case test set still can’t separate a 90% pass rate from a 94% pass rate. Write the thresholds before the first test so results can’t move them.
- Test in a sandbox and limit live exposure. Salesforce’s guidance says batch tests belong in a sandbox, never in production, and that testing can consume credits. Review a sample of live conversations by hand, name an owner before launch, and confirm every term with Salesforce and counsel.
Why a pilot needs a decision, not a demo
Gartner’s June 25, 2025 press release predicts that over 40% of agentic AI projects will be canceled by the end of 2027, and it names rising costs, unclear business value and insufficient risk controls as the causes. The analyst quoted says most current projects are early-stage experiments or proofs of concept driven by hype. I read the text on a republishing site, so check Gartner’s own page for the exact wording. The forecast is an analyst’s opinion, not a measurement, and it covers the whole market.
The release also describes a January 2025 poll of 3,412 webinar attendees, in which 19% reported significant investment in agentic AI, 42% conservative investment, 8% none and 31% were waiting or unsure. Webinar attendees aren’t a random sample, so the numbers describe an interested audience. The practical lesson is narrower: a pilot that can’t show value, cost and risk control is the kind of project the forecast describes, and that applies whether or not the forecast proves right.
A decision has 3 possible outputs. Go means the pilot met its criteria, and the next step is a production build with a budget. Extend means it misses on specific, fixable gaps, and a short second round targets only those. Stop means the use case or the platform is the wrong fit. Salesforce’s own admin guidance says that if a use case doesn’t need natural language interpretation or summarization, another tool such as Flow may suit it better.
Picking the use case
- Start with a friction log. Mike Gerholdt’s September 1, 2026 post on the Salesforce Admins blog advises keeping a log for at least a week, recording what users were trying to do, what slowed them, the workaround, how often it happens and the better outcome. That’s vendor content, but the method is cheap and it replaces opinion with evidence. A pilot chosen from the log has a known frequency and a known pain.
- Apply the fit gate. The same post treats fit as a yes or no question: does the use case require the system to interpret natural language or summarize information. If the answer is no, a deterministic tool is probably cheaper and more predictable. Not every problem needs an agent, and a pilot that proves an agent beats a simple flow on a task a flow can already do has proved very little.
- Score the 5 criteria. Gerholdt lists data readiness, business value, frequency, manageable risk and measurable outcome, each scored from 1 to 5. He describes the scorecard as a conversation starter, not a formula, and says to start with data readiness, warning that poor data means the agent would only summarize the confusion faster. Treat any total as a prompt for discussion. Record the reasons behind each score, since the reasoning is more useful than the number.
- Prefer low consequences. The manageable risk criterion asks whether the idea can be tested safely, with limited consequences if it fails. For a first pilot, that favors read-mostly tasks such as order status or policy questions over tasks that issue refunds or change records. A pilot that can only fail safely is a better teacher than a pilot that has to be perfect on day 1. Safe failure also keeps the sponsor’s trust intact.
Scope boundaries that keep it to 6 weeks
A single workflow. Girikon’s July 2026 playbook recommends a focused pilot with a single workflow, a single user group and controlled data, and it lists testing several use cases as a pitfall. The page is consultancy marketing and gives no durations or costs, but the advice matches the arithmetic of a 6-week clock. Each added workflow multiplies test cases, knowledge sources and review hours, and the schedule has no slack to absorb it.
A single channel and user group. Choose where the agent will talk and to whom. An internal group of service reps is safer than customers for a first live exposure, because mistakes are caught by people who know the answer. If customers must be involved, limit the share of traffic. Each additional channel brings its own setup and its own failure modes, so defer extra channels to the second version.
Out-of-the-box first. Salesforce Break’s July 13, 2026 summary of a conference talk recommends starting with an out-of-the-box configuration and a narrow, well-chosen first use case, then shipping a first version and a fast-follow second version. For a tightly bounded first build, VALiNTRY360’s Agentforce Quickstart page gives another relevant implementation reference before scope expands. The article is a summary of a talk and cites no data. It’s still a sound constraint, since custom code adds testing and ownership burdens that a 6-week pilot can’t carry. Standard actions can be replaced later if needed.
A written out-of-scope list. Write down what the pilot won’t do, and have the sponsor sign it in week 1. Typical entries are extra channels, new integrations, refunds, record changes and any data not already clean. The list is a defense against scope creep, which tends to arrive politely as a small request in week 3. A visible list lets the product owner say no without a debate. Keep it to a page.
Scoring candidate use cases
The table below applies Gerholdt’s 5 criteria to 3 invented candidates for a retailer’s service team. The scores are mine, on his 1 to 5 scale where 5 is stronger. I added the total column for convenience, and he says explicitly that the scorecard isn’t a formula, so read the totals as a conversation aid. The interesting rows are the low data readiness scores, which should change the plan more than the sum does.
| Candidate | Data readiness | Business value | Frequency | Manageable risk | Measurable outcome | Total |
| A: Order status questions | 4 | 3 | 5 | 5 | 5 | 22 |
| B: Return eligibility | 3 | 4 | 4 | 3 | 4 | 18 |
| C: Warranty claim intake | 2 | 5 | 2 | 2 | 3 | 14 |
Candidate A wins on frequency, safety and measurability, and its value is modest, which is acceptable for a first pilot. Before committing to the candidate, an AI readiness assessment can help expose data, governance and process gaps that would otherwise appear during the build. Candidate C has the highest value and the weakest data, and it’s rarer, so it would make a poor first test even though a success there would matter more. Candidate B sits between them. A sound sequence is to pilot A, learn how the team handles testing and ownership, and then take on B as the second version with real evidence behind it.
Success criteria written before the build
Salesforce Break’s summary advises locking measurable KPIs before building, and configuring monitoring before launch. Salesforce’s Trailhead testing guidance adds a baseline idea: each organization sets its own pass or fail line, and a suggested starting point is how accurately a human would perform the same task. Neither source gives numbers. So in the invented plan I set a human baseline of 96% accuracy from a quality sample, and a pilot target of at least 90% on batch tests.
Criteria should cover more than accuracy. For service-focused pilots, VALiNTRY360’s Agentforce for Service page provides useful context on where agent actions, escalation and service workflows meet. The invented plan adds a limit of no critical errors, where a critical error is a wrong refund amount, a privacy leak or an invented policy. It adds correct escalation on every test case that requires a human, a response time that matches the current channel, and a cost per conversation. At 4 actions of 20 credits each and $0.005 per credit, actions alone cost $0.40 a conversation, and the pilot should report the real figure.
Write the thresholds and the definition of each term before any test is run, and have the sponsor sign them. A criterion that’s defined after seeing the results will drift toward whatever the results happen to be. Also separate output measures from outcome measures: a correct answer is an output, while a customer who needn’t call back is an outcome. A 6-week pilot can report the first with confidence and only hint at the second.
What the test set can and can’t prove
Sample size. A pass rate from a finite test set has a margin of error. At an observed 90%, the normal approximation gives about plus or minus 8.3 points for 50 cases, 5.9 for 100, 4.2 for 200 and 2.9 for 400. A 90% result on 200 cases is consistent with a true rate anywhere from about 85% to 93%. To narrow the margin to 3 points you’d need roughly 384 cases, which is more than most pilots can write and review.
No failures at all. A common rule of 3 says that if you see no failures in n independent tests, the 95% upper bound on the failure rate is about 3 divided by n. A run of 200 cases with no critical errors means the true rate could still be as high as 1.5%. With 500 cases the bound is 0.6%. That’s a sobering fact for risk owners, and it argues for human review and an escalation path even when every test passes.
Coverage and tools. Trailhead says batch testing can cover large sets of scenarios in a single run, and it gives no recommended counts or pass thresholds. Test inputs can be uploaded as a CSV or generated, and each result shows the expected and actual actions and the response. It says to run test suites in a sandbox and never in production, since testing can modify CRM data, and it notes that testing can consume credits. The suite is labeled beta in that guidance.
Data and knowledge work in week 2
- Knowledge articles. An agent can only ground its answers in what the articles say. Customertimes assigns 30% of a first agent’s effort to data and grounding preparation and says most timeline overruns originate there. Check each article the pilot relies on for currency, duplicates and contradictions. In the invented plan, 60 hours of cleanup cost $5,700, which is small next to the damage a stale policy can cause. Retire any article that conflicts with another.
- Record quality. If the agent reads order or case records, duplicates and missing fields become wrong answers. Gerholdt’s data readiness question asks whether the data is accurate, current and accessible. If ownership and quality rules are unclear, Salesforce data governance services are a relevant reference for defining controls before production. A quick profile of the fields the pilot will touch, with counts of blanks and duplicates, turns that question into a number. Fix only what the pilot needs, and list the rest as production work. Keep a short log of each fix so production work can reuse it.
- Permissions. Trailhead’s evaluation questions ask whether the response is grounded in your data and tell testers to confirm the data calls, permissions and data currency. An agent that sees more than the user should is a risk, and an agent that sees less gives vague answers. Test with the real permission model, using realistic roles, and record exactly which objects and fields the agent can read. Repeat the test for each role the pilot will serve.
- Separate scoping for cleanup. Vantage Point’s generic 4 to 6 week plan notes that data cleanup is scoped separately. That’s a useful reminder: a cleanup that takes longer than a week can threaten the whole 6-week window, so find out its size in week 1. If cleanup is large, shrink the use case or move its start date, instead of squeezing the testing weeks. Decide in week 1 whether the cleanup fits the window.
A week-by-week plan
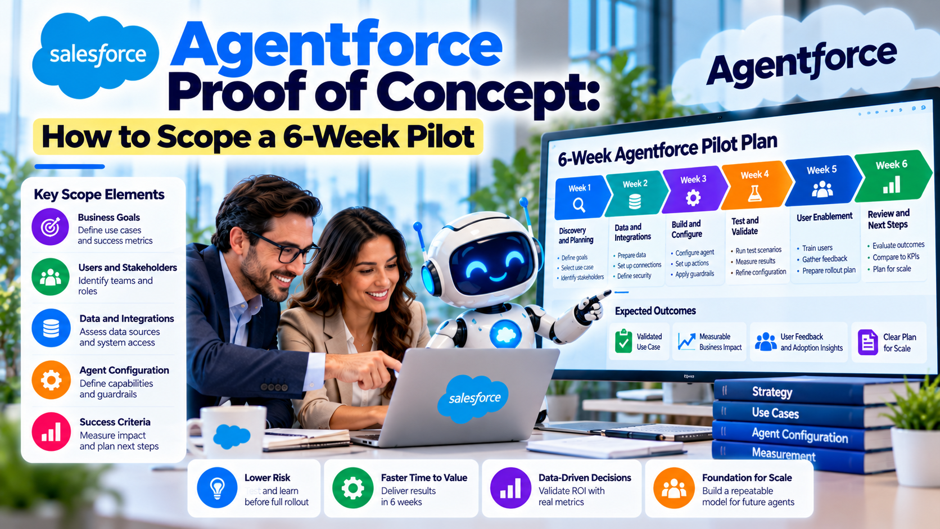
The table below lays out an invented 6-week plan for candidate A. VALiNTRY360’s Salesforce implementation services page provides a broader reference for discovery, configuration, testing, launch and post-launch work outside this pilot-sized schedule. Vantage Point’s generic plan runs about a week of discovery, 2 weeks of configuration and testing in weeks 3 and 4 before launch, and the Customertimes phases cover discovery, data, configuration, testing and rollout. My version adds a decision week and puts limited live exposure in week 5. Dates and hours are placeholders to be adjusted to your calendar and team.
| Week | Main activities | Output | Gate |
| 1 | Review friction log, lock scope, write criteria and owners | Signed scope and criteria | Sponsor approves |
| 2 | Clean knowledge and records, draft test cases | Grounding data, first 100 cases | Data readiness confirmed |
| 3 | Configure the agent, run simulated tests | Working build in sandbox | Build runs end to end |
| 4 | Batch tests, fixes, UAT with business testers | Test results, defect list | Pass rate meets target |
| 5 | Limited live exposure, sample review | Reviewed conversations | No critical errors |
| 6 | Measure against criteria, write the decision memo | Go, extend or stop | Sponsor decides |
The gates matter more than the activities. A gate that’s missed should trigger a conversation in that week, not a quiet slip into the next. If data readiness isn’t confirmed at the end of week 2, you’ve learned something expensive early, and the right move is to shrink the scope or stop. A plan that lets every week be overrun by a few days will reach week 6 with no live data and no decision.
Roles and hours for the pilot team
- Product owner and sponsor. Salesforce Break’s summary says to name a product owner and an executive sponsor who is actively engaged, because unowned projects drift. For the operating model after the pilot, Agentforce Managed Services is a relevant reference for ongoing ownership and support. In the invented plan the owner spends 6 hours a week, or 36 hours total, at an assumed $110 an hour. Their job is to protect the scope, accept the test results and say go, extend or stop. The sponsor’s time is smaller but non-negotiable.
- Builder. A partner architect or developer configures the agent, writes the actions and fixes defects, at an invented 30 hours a week for 180 hours at $175. Credera’s lessons advise pairing the client team on configuration and prompt design, since an MVP the client can’t maintain may stall. Build that pairing into the plan, and ask the builder to document decisions as they’re made. The same person should write the test cases that guard each action.
- Admin and data owner. An internal admin supports permissions, sandbox setup and data fixes, at an invented 12 hours a week for 72 hours at $95. A knowledge owner updates the articles. These people know where the data problems hide, and their calendar availability is a common cause of slipped weeks, so ask for their time in week 1. Their sign-off on permissions and data fixes should be a formal gate, not an afterthought in week 4.
- Business testers. Salesforce Break’s summary says to complete user acceptance testing with business subject-matter experts, not IT alone. The invented plan gives them 40 hours at $85, mostly in weeks 2 and 4. They write realistic cases, judge answers against policy and find the edge cases that a builder wouldn’t think to try. Their review also builds trust in the result. Pay attention to which cases they find hardest, because those are the real edge cases.
Budget: labor and credits
The invented labor adds up to 388 hours and $51,400: $31,500 for the builder, $6,840 for the admin, $3,960 for the product owner, $3,400 for business testers and $5,700 for knowledge cleanup. Credits are small by comparison. The Salesforce rate card dated August 31, 2026 lists a sandbox action at 16 credits, and the Agentforce pricing page lists $500 per 100,000 credits, which is $0.005 each. A test set of 200 cases at 4 actions each, run 5 times, uses 64,000 credits, or $320.
Limited live exposure adds more. If 500 conversations each use 4 actions at 20 credits, that’s 40,000 credits, or $200. The pilot’s credit total is $520, about 1% of the $51,920 combined cost, and a 2 times buffer is still only $1,040. The lesson is that labor drives pilot cost, and credits become important only at production volume. At 6,000 conversations a month with 4 actions each, actions would cost $2,400 a month, which is the number a production decision needs.
Caveats apply in 2 places. First, Trailhead says test suites can consume requests or credits and refers readers to Salesforce’s billing documentation for amounts, so I can’t confirm how every testing tool is metered. Macha, a competing vendor, also says sandbox test runs consume credits. Second, the rate card shows credits only, so the dollar values are my arithmetic from the pack price. Ask your account team in writing how pilot usage will be billed and whether any usage is waived. Treat those numbers as a floor for planning, not a quote.
Safe rollout during the live week
Limit exposure. The invented plan sends 500 conversations to the agent, about 8.3% of a 6,000-a-month volume. That’s enough to see real phrasing and small enough to contain a failure. An internal-first approach is safer still: let service reps use the agent to draft answers that they review, as Vantage Point describes for an insurance and payroll brokerage, then move to customers only if the results hold. For customer-facing pilot design, VALiNTRY360’s Agentforce Digital Engagement page is a useful reference for testing and controlled deployment. Define the stop condition before the week begins.
Review a sample. Reading every live conversation is rarely feasible, so review a random sample. If 100 of the 500 are reviewed and 90 are correct, the observed rate is 90%, with a 95% interval of roughly 83% to 94%. A sample of 100 can’t prove a 90% target, but it can reveal a pattern of errors. Include every conversation that escalated or ended early, because those are where the agent’s weaknesses show.
Guardrails and monitoring. Salesforce Break’s summary advises setting guardrails for escalation, off-topic questions and PII handling, testing escalation logic under realistic load instead of only the happy path, and configuring monitoring before launch. Trailhead notes that its session tracing view, which shows reasoning and action details, requires Data 360. If you need that depth of tracing, price the dependency early, since it changes both scope and cost. Decide who watches the dashboards each day.
Decision rules at the end of week 6
The table below shows invented rules for the memo that closes the pilot. The thresholds are placeholders, set to match the criteria in the earlier section, and they should be adapted before week 1 and then left alone. What matters is that the rule exists before the results do. When the numbers land between rows, the sponsor should decide, and the memo should record the reason so the choice can be reviewed later.
| Outcome | Invented rule | Next step |
| Go | At least 90% pass on batch tests, no critical errors in live sample, escalation correct on all required cases | Fund a production build with owners and a run budget |
| Extend | Between 80% and 90%, or a critical error with a clear fix | A 2-week second round limited to named gaps |
| Stop | Under 80%, repeated critical errors, or data that can’t be fixed in the window | Write up lessons; consider a simpler tool |
A written Extend option guards against a common trap, which is an endless pilot. If the pilot passes and needs a fuller build, AI agent development solutions provide a relevant next-stage reference without changing the decision rule itself. Limit extensions to a single round with a fixed length and a narrow target. Stop deserves equal respect: a pilot that ends with a well-argued no has saved the cost of a failed production project, which is precisely the outcome Gartner’s forecast describes. Share the memo with the people who gave their time, including the business testers.
Why published timelines disagree
Customertimes arithmetic. Customertimes says a first agent on reasonably clean data takes 6 to 8 weeks. Its phase durations are 1 to 2 weeks for use-case selection, 2 to 4 for data preparation, 1 to 2 for configuration, 2 to 3 for testing and 1 to 2 for rollout. Those add up to 7 weeks at the low end and 13 at the high end if run in sequence. Either the phases overlap or the total is hopeful, and the page doesn’t say which.
Narrower plans. Vantage Point describes a generic 4 to 6 week go-live with a week of discovery, 2 of configuration and testing in weeks 3 and 4, with data cleanup scoped separately. VALiNTRY360’s Agentforce AI consulting page is another relevant source to compare when a partner proposes a compressed timeline. Summit Tech 360 lists 2 to 4 weeks per agent for a quickstart, though it shows some configuration as an additional service. Macha attributes a 4-week claim to a 2025 Salesforce datasheet and calls it marketing. None of the plans measures outcomes, so treat all of the durations as vendors’ estimates.
A pilot isn’t production. A 6-week pilot with a narrow scope and limited exposure is a different thing from a production agent with integrations and full volume. Comparing them produces confusion. A Vantage Point page with a URL that suggests a 6-week healthcare Agentforce deployment says it has no published Agentforce case study, so I couldn’t use it as evidence. Use published timelines to frame questions to your partner, not as a promise.
Governance and risk items to settle early
- Approvals and owners. Salesforce Break’s summary advises defining required approvals, a governance structure and applicable policies up front, even in unregulated sectors, and involving legal, data governance and security early. That costs little in week 1 and a great deal in week 5. Name who can approve the live exposure, who can stop it and who is on call if the agent says something wrong. Write the names into the plan, beside the roles.
- PII and guardrails. Decide what the agent may never say or do, and what data it must never expose. Test those boundaries on purpose, with prompts designed to provoke failures. Gartner lists insufficient risk controls as a cause of canceled projects, so the pilot should produce evidence of control, such as the test log and the review sample, along with the demo. Keep the prompts used for these tests in the test set for later reuse.
- Pricing model. Salesforce’s pricing page says Flex Credits and per-conversation pricing can’t be used in the same org, and that switching requires swapping the existing SKUs. Salesforce also publishes its current Agentforce and Data 360 rate cards separately, so use the rate card that applies when the pilot is budgeted. A pilot is a chance to measure actions per conversation, which decides which model is cheaper. Capture the number in the pilot report, and confirm the terms with Salesforce. Ask Salesforce which model fits the expected conversation length, and get the answer in writing before the pilot report is final.
- Test data and environments. Trailhead warns that testing can modify CRM data and says to use sandboxes only. A SalesforceBen article by a Capgemini marketing architect advises keeping environments aligned, based on experience and without data, but the point is reasonable: a sandbox that differs from production in sharing rules or data gives results that don’t transfer. Document the differences and discount the results accordingly. Use synthetic or masked data in the sandbox, and record where the pilot’s data came from.
What happens after the decision
If the decision is go, write the second version’s roadmap before the first version ships, as Salesforce Break’s summary advises. Assign the post-launch roles it lists: an agent owner, a supervisor who monitors metrics and a technical lead. Credera’s article warns that a build the client team can’t maintain may stall, so confirm that someone inside the company can edit instructions and read test results without the partner. A handoff note with the prompts, tests and known gaps saves weeks later.
The production budget should come straight from the pilot. Use the measured actions per conversation, the real review hours and the defect rate to size the build, and let the data replace the invented figures in this guide. The pilot’s cost per conversation also decides the pricing model. If the agent averages 4 actions, credits cost $0.40 a conversation on actions alone, against the $2 per-conversation rate Salesforce lists, and the break-even is 20 actions.
If the decision is extended or stopped, say so plainly and record why. A short report that lists the criteria, the results, the cost and the reasons gives the next team a head start, and it protects the sponsor from the suspicion that the pilot was wasted. Keep the test set, because it’s reusable for the next use case. Ask whether the friction log still shows other candidates, and start the next pilot from there, with the lessons built in. Share the result with every group that gave time to the pilot.
FAQs
What’s a good scope for a 6-week Agentforce pilot?
A single workflow, a single user group, a single channel and controlled data. Girikon recommends that shape, and Salesforce Break’s summary advises an out-of-the-box configuration with a narrow first use case. Choose a task with high frequency, measurable outcomes and low consequences if it fails, such as order status. Write an out-of-scope list in week 1, and have the sponsor sign it along with the success criteria. Keep the out-of-scope list short and signed.
Can an Agentforce pilot really be done in 6 weeks?
For a narrow scope with clean data, it’s plausible, but I found no measured evidence. Vantage Point describes a 4 to 6 week go-live plan with data cleanup scoped separately, and Customertimes says 6 to 8 weeks for a first agent, though its phase durations add up to 7 to 13 weeks. Treat both as vendor estimates. Find out the size of the data cleanup in week 1. Plan for some slippage too.
How much does a pilot cost?
In my invented plan, 388 hours cost $51,400, and credits add about $520, for roughly $51,920. The hours, rates and credit volumes are all placeholders. Labor dominates, so the builder’s rate and the cleanup effort matter most. Salesforce’s pricing page lists $500 per 100,000 credits, and its rate card lists sandbox actions at 16 credits. Ask your account team how pilot usage is billed. Confirm the billing treatment of test usage with Salesforce before you commit to a budget.
How many test cases do I need?
Salesforce’s guidance doesn’t recommend a number, saying only that batch tests can cover dozens or hundreds. Statistics help: at a 90% observed pass rate, 200 cases give a margin of about 4.2 points, and roughly 384 cases would give 3. A run of 200 cases with no critical errors still allows a true rate near 1.5%. Pick a count you can write and review well, and add human review of live conversations. Write fewer, better cases.
What success criteria should I set?
Set accuracy against a human baseline, a limit of no critical errors with a written definition, correct escalation, response time and cost per conversation. Trailhead suggests using how accurately a human performs the task as a starting baseline, and Salesforce Break advises locking KPIs before building. My thresholds of 90% pass and a 96% human baseline are invented. Get the sponsor’s signature on the criteria before any test runs. Define critical error in writing before the first test.
Should the pilot run in production?
Run batch tests in a sandbox, never in production, since Trailhead warns that testing can modify CRM data. Limited live exposure in week 5 is reasonable if the agent is read-mostly, traffic is capped and humans review a sample. An internal-first stage, where reps review drafts, is safer. Settle approvals, stop conditions and an on-call owner with legal and security before the live week begins. Keep customer exposure small, capped and easy to reverse.
Do I need Data 360 for a pilot?
Not necessarily. Customertimes says a first agent grounded in CRM records and knowledge articles doesn’t require it. Trailhead notes, though, that session tracing, which shows detailed reasoning and action data, requires Data 360. If you need that level of visibility, price the dependency before you start. Confirm with Salesforce which features your edition includes and how any Data 360 usage would be billed. Salesforce can say which of your licenses already include it, if any.
What happens if the pilot fails?
A failed pilot is a result, provided it was set up to produce a clear answer. Record the criteria, the test outcomes, the cost and the reasons, and decide whether the cause was the use case, the data, the configuration or the platform. Gartner’s forecast cites rising costs, unclear value and weak risk controls as reasons projects are canceled, so a clear stop can save money. Keep the test set, and start the next pilot from the friction log.