

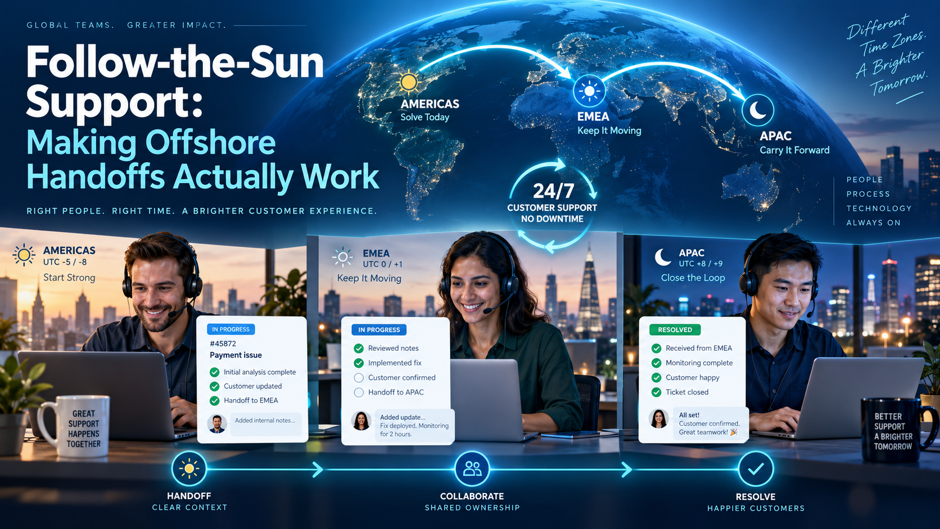
A customer opens a ticket at 4:45pm in New York, gets a thoughtful first response, and goes home for the evening assuming someone is still working the problem. What actually happens next determines whether follow-the-sun support becomes a genuine advantage or a quiet source of customer frustration: the ticket either transfers cleanly to the next region with full context intact, or it lands on a new agent’s queue as an unfamiliar case they have to reconstruct from scratch, forcing the customer to re-explain everything the moment they reply the next morning. The difference between those 2 outcomes isn’t the time zone strategy. It’s whether the handoff itself was actually built to work, or simply assumed to work because the org chart shows coverage across 3 regions.
Follow-the-sun support distributes teams across time zones so that each region works its own normal daytime hours, and support responsibility transfers from one region to the next as each workday ends. Done well, it delivers genuinely continuous coverage without asking anyone to work a permanent night shift, and Zendesk’s 2026 CX Trends research found that 74% of consumers now expect customer service to be available 24/7. Done poorly, it produces exactly the fragmented, context-free experience customers already associate with being bounced between departments, except now the bouncing happens across continents instead of desks.
This guide focuses specifically on the mechanics that separate a follow-the-sun model that genuinely works from one that looks good in a coverage map but falls apart at every shift boundary: what a clean handoff actually requires, why overlap windows matter more than hard cutoffs, which tools belong in the stack and which don’t, and how to measure whether the handoffs are actually holding up under real volume.
TL;DR
| Element | What it requires |
| Regional coverage design | Time zones chosen to complement each other across a 24-hour cycle, not just spread arbitrarily across continents |
| Overlap windows, not hard cutoffs | Real overlap at shift boundaries so context transfers through live conversation, not a note left behind at a fixed cutoff time |
| A structured handoff protocol | A consistent template covering status, active issues, actions taken, and next steps for every active case that meets the defined handoff criteria, with more detail for higher-risk cases |
| One shared system of record | A single ticketing or incident platform every region reads from and writes to, not separate regional tools that don’t sync cleanly |
| Time-zone-aware routing | Alerts and tickets automatically assigned to whichever region is actually online, not blindly paged to whoever’s on a rotation list |
| Handoff-specific metrics | Reopened tickets, resolution time at the boundary, and CSAT on handed-off cases tracked separately from overall team metrics |
| A phased rollout | One handoff point launched and stabilised before the next is added, not the entire model flipped on simultaneously |
None of these elements works in isolation. A perfect regional coverage map with no structured handoff protocol produces the same fragmented experience as a great handoff template used inconsistently, and the sections below work through each piece in enough depth to actually implement it, rather than leaving any single component as a vague aspiration.
What Follow-the-Sun Actually Solves, and What It Doesn’t
Before getting into handoff mechanics, it’s worth being precise about what problem this model is actually solving, because misunderstanding the goal is exactly where several of the most common implementation mistakes originate, often before a single shift has even been scheduled or a single region hired for.
The Real Alternative Isn’t “No Coverage,” It’s Burnout
The naive alternative to follow-the-sun isn’t leaving customers without support outside a single region’s business hours. It’s asking one team to absorb night and weekend shifts on a rotating basis, which reliably produces burnout, elevated turnover, and degraded quality precisely during the hours when fewer senior staff are available to catch mistakes. Follow-the-sun exists specifically to deliver continuous coverage without forcing any single team to carry that burden, which is why regional teams working their own normal daytime hours is the defining feature of the model, not an incidental detail.
What Follow-the-Sun Doesn’t Automatically Fix
Distributing teams across time zones doesn’t automatically produce consistent quality, consistent tone, or fast resolution on its own. Coordinating schedules, coverage gaps, and regional holidays across 3 or more teams requires genuinely more day-to-day management than a single-region team ever deals with, and standing up a second or third regional presence costs meaningfully more upfront than simply extending one existing team’s hours. The model only pays for itself once ticket volume, complexity, and geographic customer distribution justify that additional coordination overhead, which is why follow-the-sun tends to fit global, high-volume, or genuinely complex support operations far better than it fits a business whose tickets cluster almost entirely inside one region’s business hours already.
Designing Regional Coverage That Actually Complements Itself
The starting point for any follow-the-sun model is choosing regions whose working hours genuinely complement each other across a full 24-hour cycle, rather than simply having offices that happen to exist in different countries with no real thought given to how their respective schedules actually interlock with one another.
A Common 3-Region Pattern
| Region | Local shift and UTC reference | Role in the cycle |
| Americas (US Pacific) | 8am to 5pm PT; 15:00-00:00 UTC in PDT, 16:00-01:00 UTC in PST | Covers Americas daytime; overlaps EMEA for about 1 hour and APAC for about 1 hour across daylight-saving changes |
| EMEA (UK) | 8am to 5pm UK time; 07:00-16:00 UTC in BST, 08:00-17:00 UTC in GMT | Covers EMEA daytime; overlaps APAC for 1 to 2 hours and Americas for about 1 hour across clock changes |
| APAC (Singapore) | 8am to 5pm SGT; 00:00-09:00 UTC year-round | Covers APAC daytime; overlaps EMEA for 1 to 2 hours and Americas for about 1 hour, closing the 24-hour cycle |
This pattern, sometimes described as a continental 3-shift rotation based on Coordinated Universal Time, gives each region a predictable, standard workday while collectively producing genuine 24-hour coverage. The exact hours shift depending on which specific countries and offices are involved, but the underlying principle stays the same: each region’s shift should overlap meaningfully with the region on either side of it, not simply end where the next one begins.
Why the Specific Country Matters as Much as the Time Zone
Nearshore hubs in locations like Colombia, El Salvador, or Jamaica align naturally with US daytime hours and support real-time collaboration with domestic teams. EMEA hubs in locations such as Morocco, Albania, or Kosovo often serve specifically as the bridge shift between the Americas and Asia-Pacific windows. Offshore hubs in the Philippines or India frequently anchor the overnight coverage window precisely because their own daytime hours align with the gap Western regions leave open. Choosing locations based purely on cost without considering how their working hours actually interlock with the rest of the coverage plan produces gaps that no amount of process discipline can fully compensate for later.
Why Overlap Windows Matter More Than Hard Cutoffs
Overlap design is one of the most important choices in a follow-the-sun model. The question is whether shift boundaries include genuine overlap or simply hand off at a fixed cutoff time, and that choice affects the quality of every handoff that happens afterward, day after day.
What a Hard Cutoff Actually Produces
A hard cutoff, where one region’s shift ends at 4pm UTC and the next region’s begins at 4pm UTC with no shared working window between them, forces every handoff to happen asynchronously through written notes alone. The outgoing team documents what they can before logging off, and the incoming team has to reconstruct context entirely from that written record, with no opportunity to ask a clarifying question or flag something the notes didn’t fully capture. This structure works acceptably for simple, low-stakes tickets and breaks down consistently for anything genuinely complex or actively escalating.
What a Real Overlap Window Enables
An overlap window, even a relatively short one, changes the handoff from a one-way document drop into an actual conversation. The outgoing team can walk the incoming team through active cases directly, answer questions in real time, and flag anything the written notes might not fully convey, such as a customer’s specific frustration level or a technical detail that’s easy to miss in a summary. This live handoff period is specifically what allows context to transfer with genuine fidelity rather than degrading with each written retelling, and it’s a common differentiator between follow-the-sun implementations that hold up under real volume and ones that quietly accumulate handoff-related failures.
How Much Overlap Is Actually Necessary
The right overlap window depends on ticket complexity and volume, but even a 30-to-60-minute shared window at each boundary meaningfully improves handoff quality compared to a hard cutoff, since it creates space for the highest-priority or most complex active cases to be discussed directly rather than relying entirely on documentation. Teams handling genuinely complex, multi-step technical issues or active incidents typically benefit from a longer overlap than teams handling primarily simple, self-contained requests, and the right window size is usually something a team refines over its first full quarter of operation rather than something that can be perfectly predicted in advance.
What a Structured Handoff Protocol Actually Requires
Beyond the overlap window itself, the specific content and format of what gets communicated at every single handoff determines whether context genuinely transfers cleanly or instead quietly leaks a little more with each shift change, until eventually nobody quite remembers the original detail that actually mattered in the first place.
The core elements a handoff template should capture for every active case that meets the defined handoff criteria:
- Current system or service status, confirming what’s healthy, what’s degraded, and what’s on a temporary workaround, so the incoming team starts with an accurate baseline rather than assuming everything is normal
- Every active case that meets the defined handoff criteria, including the customer’s history, what’s already been tried, the current working hypothesis, and the specific next step, not just a case number and a vague note to “follow up”
- Anything time-critical that must happen during the incoming shift, flagged explicitly rather than buried inside a longer list where it’s easy to miss
- Changes made during the outgoing shift, including configuration changes, escalations initiated, or commitments made to a customer that the next team needs to honour
- Contextual information relevant beyond the immediate shift, such as a customer known to be especially sensitive right now, or a recurring issue pattern worth watching for over the coming days
Why Consistency Matters More Than Sophistication
A simple, consistently used handoff template outperforms an elaborate one that gets skipped or abbreviated under pressure, because the moments when a handoff matters most, during a genuine incident or an unusually busy shift, are exactly the moments when an inconsistently applied process is most likely to break down. The goal isn’t building the most comprehensive possible template; it’s building one specific enough to be genuinely useful and simple enough that the outgoing team actually completes it fully even when they’re rushing to finish their shift.
The Difference Between a Handoff Log and a Real Handoff
Use the written record for facts that must survive a complete handoff. Capture current status, actions already taken, customer commitments, the next step, and the named owner. Use the live overlap for ambiguity, risk, exceptions, and questions that need clarification before ownership moves. After the conversation, the written record remains the source of truth for the incoming team. This keeps factual history durable while using live discussion for details that genuinely benefit from questions.
Building the Technology Stack That Handoffs Actually Depend On
A well-designed handoff protocol still fails if the underlying technology doesn’t genuinely support it, and several specific, recurring tooling gaps show up repeatedly across implementations that struggle to make follow-the-sun coverage actually work in practice, regardless of how carefully the underlying process itself was originally designed on paper.
The Non-Negotiable Layer: One Shared System of Record
Every region needs to read from and write to the same ticketing or incident platform, whether that’s a customer support tool like Zendesk or Freshdesk, or an incident management platform for technical operations. If one region uses a different tool or can’t see the full history of a case, the handoff breaks immediately regardless of how good the written protocol is, because the incoming team is working from incomplete information no template can fully compensate for.
What Belongs in the Stack and Why
| Tool category | What it needs to provide | Common mistake to avoid |
| Ticketing or incident platform | A single, shared view of every case’s full history across every region | Running separate regional instances that don’t sync in real time |
| Alerting and routing | Time-zone-aware escalation that assigns ownership automatically as shifts change | Treating a chat tool like Slack as an alerting system, when it isn’t built for guaranteed delivery or escalation |
| Real-time communication | A space for the live overlap conversation and quick clarifying questions between regions | Relying entirely on asynchronous comments left inside individual tickets |
| Shared knowledge base | One source of truth every region pulls troubleshooting steps and product information from | Letting each region build its own informal, undocumented tribal knowledge over time |
Why Automated Routing Matters as Much as the Handoff Itself
Beyond the platforms themselves, automated, time-zone-aware routing determines whether new incoming issues land with the correct, currently-active region without manual intervention. Configuring escalation paths that assign ownership within the response target defined for that priority and channel, with tighter escalation for critical incidents, removes one of the most common sources of delay in a follow-the-sun model: a ticket or alert sitting unassigned because it landed during a genuine gap between regions, or because it was routed to a team that’s already gone home for the day.
Measuring Whether Handoffs Are Actually Working
A follow-the-sun model can look successful in an aggregate dashboard while quietly failing at every shift boundary, which is exactly why handoff-specific metrics need to be tracked separately from overall team performance rather than blended into a single, reassuring company-wide number that hides where the real weakness sits.
The metrics that reveal handoff quality specifically:
- Reopened ticket rate on handed-off cases, compared against the reopened rate for cases resolved entirely within a single region’s shift, since a meaningfully higher reopen rate on handed-off cases is one of the clearest signals that context isn’t transferring cleanly
- Resolution time delta at the boundary, measuring whether cases that cross a shift boundary take meaningfully longer to resolve than comparable cases that don’t, which isolates the specific cost the handoff itself is adding
- CSAT specifically on handed-off conversations, tracked separately from overall CSAT, since customer satisfaction on cases that crossed a region boundary is often the first place quality problems become visible before they show up in any other metric
- Time-to-first-touch after handoff, confirming the incoming region is actually picking up transferred cases promptly rather than letting them sit while the new shift settles into its own queue
- Handoff completion rate, tracking what percentage of shifts actually completed the full structured handoff protocol rather than an abbreviated version, since this metric often explains variance in every other number on this list
Why These Metrics Show Problems Before Anything Else Does
Watching how conversations specifically perform at the shift boundary tends to reveal a follow-the-sun model’s genuine weak points well before those same weaknesses ever show up in any broader, aggregated metric, because the boundary is precisely where the process is most likely to be stressed. A team that looks healthy on overall resolution time and CSAT can still be quietly accumulating a handoff-specific problem that only becomes visible once these boundary-specific numbers are isolated and tracked on their own.
Handling the Human Side of Cross-Region Handoffs
Process design and tooling solve most of the mechanical problems in a follow-the-sun model, but a meaningful share of handoff friction traces back to something no template or platform fully addresses on its own: the genuine cultural, linguistic, and communication differences between teams working in different countries and, often, different first languages.
Why Consistency Between Regions Is Harder Than It Sounds
Customers interacting with a follow-the-sun support model across multiple consecutive days frequently notice when tone, terminology, or overall problem-solving approach shifts noticeably between regions, even when every individual team is technically following the same documented process on paper. This inconsistency isn’t usually a training failure in any single region; it’s the natural result of different teams developing their own conventions and shorthand over time unless something actively works against that drift. Regular cross-region calibration, shared training materials, and periodically reviewing a sample of handed-off conversations together as one combined team are what keep this consistency from eroding gradually as each region’s own local habits accumulate.
Building Genuine Working Relationships Across Time Zones
Teams that only ever interact through written handoff notes and ticket comments tend to develop a weaker working relationship than teams who have some regular opportunity for real-time interaction, even if that interaction happens only during the daily overlap window. Some organisations deliberately build in periodic all-hands calls that rotate meeting times specifically so no single region always bears the burden of the least convenient time slot, and pairing new hires in one region with an experienced counterpart in another during onboarding helps build the kind of informal trust and familiarity that makes day-to-day handoffs smoother even when nothing has gone wrong yet.
Why Coordination Overhead Is a Real, Ongoing Cost, Not a One-Time Setup Expense
Organisations planning a follow-the-sun rollout frequently and consistently underestimate how much ongoing management coordinating 3 or more regional teams actually requires, well past the point where the initial launch has already concluded. Regional holidays that don’t align across countries, differing employment regulations affecting scheduling flexibility, and the simple practical challenge of scheduling a meeting that works reasonably well across widely separated time zones all add a genuine, recurring management burden that doesn’t disappear once the initial rollout is complete. Budgeting for this ongoing coordination cost explicitly, rather than treating it as a one-time setup expense that resolves itself after launch, produces a more realistic picture of what the model actually costs to sustain well.
Rolling Out Follow-the-Sun Without Breaking Everything at Once
Given how much can go wrong at a handoff boundary, the rollout sequence matters just as much as the eventual steady-state design itself, and most successful implementations deliberately resist the temptation to launch the entire model simultaneously across every region and every ticket type at once.
The practical rollout sequence that consistently works better than a full launch:
| Step | Action | Why it matters |
| 1 | Roll out one handoff point at a time rather than flipping the entire multi-region model on all at once | Gaps and failure patterns become visible and genuinely correctable before they touch every customer interaction simultaneously |
| 2 | Pilot the new handoff process with a limited subset of ticket types or a specific customer segment | Gives the team a controlled environment to catch problems early while the stakes of any individual failure stay low |
| 3 | Watch the boundary-specific metrics closely during the pilot period | The handoff boundary is precisely where early warning signs tend to appear first, well before showing up anywhere else |
| 4 | Adjust shift windows, overlap length, and the handoff template repeatedly during the first several months | Genuine production volume and real edge cases surface issues no amount of upfront planning could have fully anticipated |
| 5 | Keep the pilot active until handoff completion, reopen rate, boundary resolution time, and routing errors remain within target across several review cycles | Stability is demonstrated by sustained results across review cycles, not by reaching a fixed calendar milestone |
Why Rushing the Rollout Backfires
A model launched entirely all at once, across every region and every ticket type simultaneously, makes it genuinely difficult to isolate which specific handoff point is actually causing a given problem when something eventually goes wrong, since multiple brand-new processes are all running for the first time together at once. A phased rollout isolates variables cleanly, which is precisely what makes it possible to diagnose and fix a specific weak point directly, instead of facing a confusing tangle of simultaneous, overlapping issues with no clear, obvious starting point for the fix.
When Follow-the-Sun Isn’t the Right Model
Not every support or operations team genuinely benefits from this structure, and recognising when it’s simply overkill prevents an organisation from absorbing significant, ongoing coordination overhead for a problem that a considerably simpler, single-region model would have solved just as well from the very start of the effort.
Follow-the-sun tends to fit poorly when:
- Ticket volume clusters almost entirely within a single region’s business hours already, meaning the coordination overhead of standing up additional regional teams produces little genuine coverage benefit relative to its cost
- The support or operations function is small enough that a single, well-staffed team with an on-call rotation for genuine after-hours emergencies covers the actual need without requiring a second or third full regional presence
- The product or service doesn’t have a genuinely global customer base, making round-the-clock coverage a solution to a problem the business doesn’t actually have in practice
- The organisation lacks the operational maturity to maintain consistent process, tooling, and quality standards across multiple regions simultaneously, since a follow-the-sun model amplifies existing process weaknesses across every region rather than somehow fixing them through geographic distribution alone
No fixed number of these factors determines the decision. Weigh each one against actual ticket distribution, SLA requirements, customer geography, staffing cost, and the organisation’s ability to maintain consistent cross-region operations. The right model depends on the combined operating picture, not on reaching an arbitrary count of warning signs.
In these situations, extending a single team’s coverage window, adding a lean on-call rotation for genuine emergencies, or investing more heavily in self-service and automated resolution typically delivers considerably more value than the upfront cost and ongoing coordination burden a full multi-region follow-the-sun model would otherwise demand.
FAQs
How long does it typically take before a follow-the-sun model stops requiring constant adjustment?
Stabilisation should be judged by performance rather than a fixed number of weeks. Keep the pilot in active review until handoff completion, reopen rate, boundary resolution time, and routing errors remain within target across several review cycles. Early versions will still expose gaps that were not visible during planning, such as an overlap window that is too short for the actual case complexity, a missing handoff field, or a routing rule that misses a specific edge case. Treat those findings as inputs to the next review cycle rather than assuming the model is stable because a calendar milestone has passed.
What’s a common reason follow-the-sun handoffs fail in practice? Incomplete context transfer is a common failure pattern across implementations. This shows up in a few specific, recurring forms: a written handoff note that’s technically completed but too thin to be genuinely useful, a hard cutoff with no live overlap window forcing every handoff to rely entirely on that thin documentation, or separate regional tools that don’t give the incoming team full visibility into a case’s actual history. Each of these traces back to the same underlying problem: the incoming team simply doesn’t have what they need to pick up exactly where the previous team left off, no matter how well-intentioned the outgoing team’s effort was.
Does follow-the-sun always require offshore or international teams specifically?
Not necessarily, though international distribution is the most common way organisations achieve genuine time zone coverage across a full 24-hour cycle. Some organisations achieve a version of follow-the-sun using domestic teams spread across different time zones within a single country, though this typically provides a narrower coverage window than a genuinely global distribution across 3 or more continents would deliver, simply because fewer total hours are covered by teams spread across a smaller geographic range. The core principle, regional teams working their own standard hours while collectively producing continuous coverage, applies regardless of whether the regions involved cross international borders or simply span different time zones within one country.
How should a team decide on the right overlap window length?
Start with a baseline of 30 to 60 minutes at each shift boundary and adjust based on what the boundary-specific metrics reveal during the first few months of operation. Teams handling primarily simple, self-contained tickets can often function well with a shorter overlap, while teams handling complex technical issues, active incidents, or cases requiring significant context typically need a longer window to transfer that context with real fidelity. The right answer is rarely obvious in advance, and it tends to emerge gradually from watching reopened ticket rates and resolution time delta at the boundary carefully during the pilot period described earlier in this guide.
Should every ticket or case go through the full structured handoff protocol, or only high-priority ones?
Most implementations that work well apply the handoff protocol consistently to every active case that meets defined handoff criteria, with more detail for higher-risk cases. Those criteria can include priority, customer impact, unresolved work, or time-sensitive commitments. Reserving detailed handoffs only for the most severe cases can leave moderate-priority customer issues under-documented, while forcing the full protocol onto every routine item adds work without improving continuity. The rule should be clear enough that every region makes the same handoff decision.
What role does a shared knowledge base play in making handoffs work?
A shared, well-maintained knowledge base ensures every region works from the same underlying product information and troubleshooting steps, which reduces how much case-specific context actually needs to be transferred at each handoff in the first place. When every region already shares the same foundational knowledge, the handoff itself only needs to cover what’s genuinely specific to that individual case, rather than also needing to re-explain baseline product or process information that should already be common, well-documented knowledge across every region involved in the rotation.
Can AI-assisted tools meaningfully improve handoff quality?
Emerging tooling that automatically summarises case history, flags inconsistencies between what a ticket’s notes say and its actual status, or drafts a structured handoff summary from raw activity logs is starting to reduce some of the manual burden of thorough documentation, particularly during high-volume periods when agents are more likely to rush or abbreviate handoff notes. These tools work best as an assist that speeds up and improves consistency in an already well-defined handoff process, rather than as a replacement for the underlying protocol, overlap windows, and shared tooling that actually make follow-the-sun support work in the first place, since no amount of automation compensates for a process that was never properly designed to begin with.